
Your coding agents stop re-debugging what you already fixed.
Claude Code, Codex, Cursor and 35 more agents already save every session to disk.
deja indexes all of it, months back, and hands the part that matters
to whichever agent is working now.
English | 简体中文 | 繁體中文 | 日本語 | 한국어 | Español | Português | Français | Deutsch | Русский | Türkçe | हिन्दी
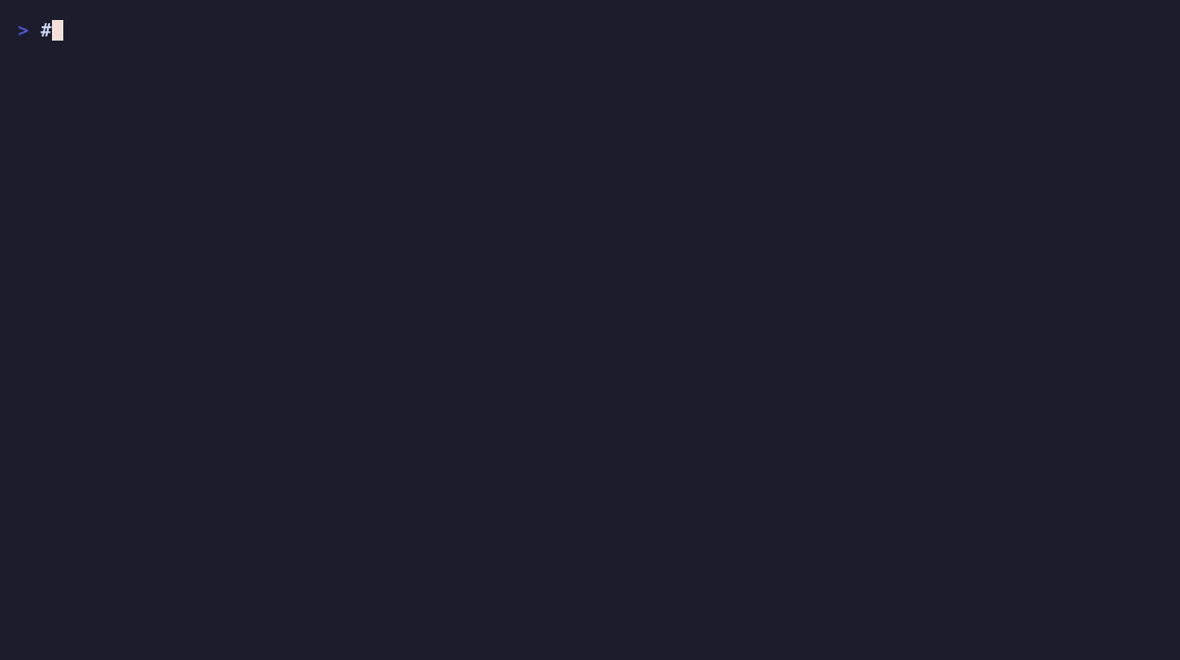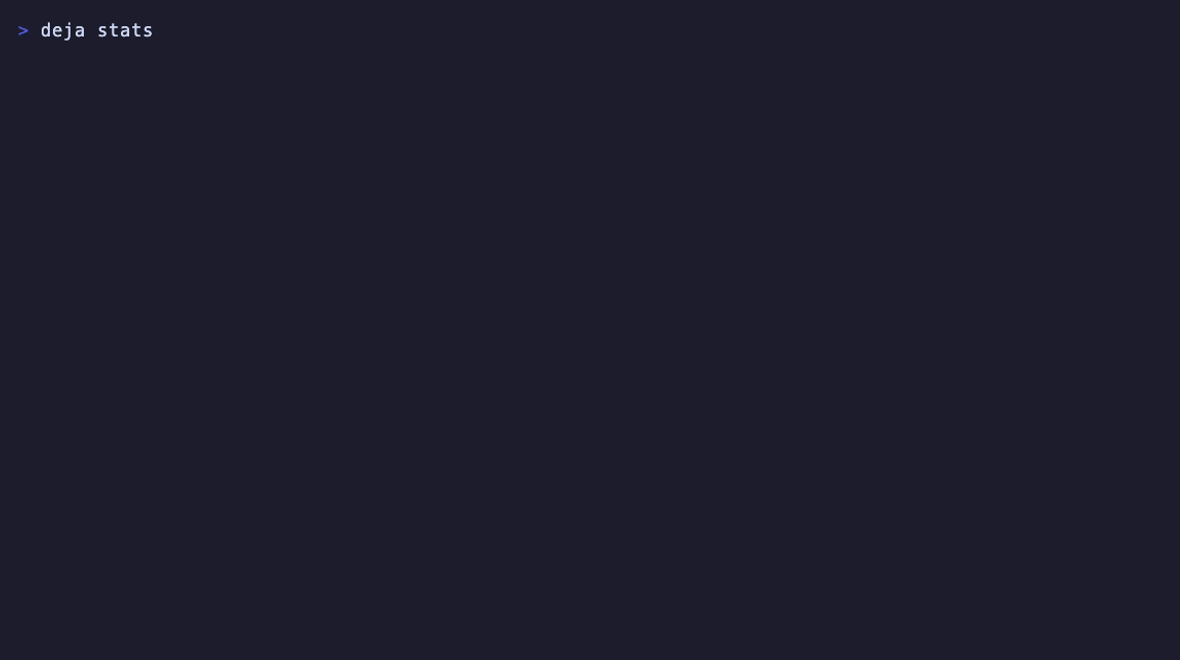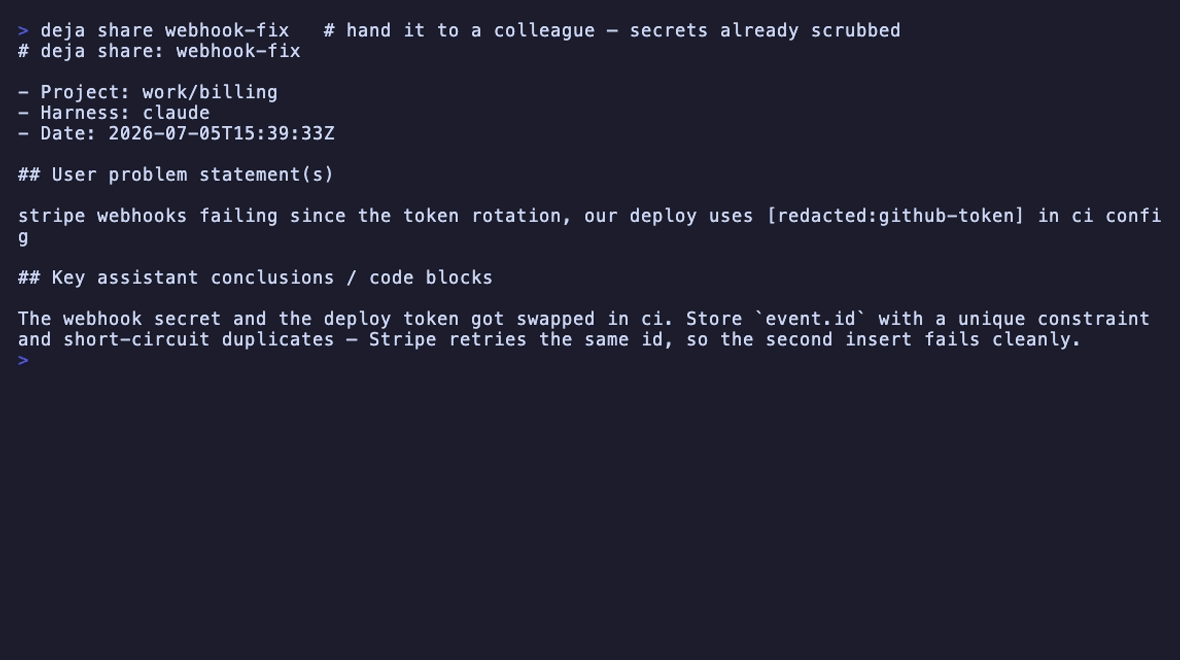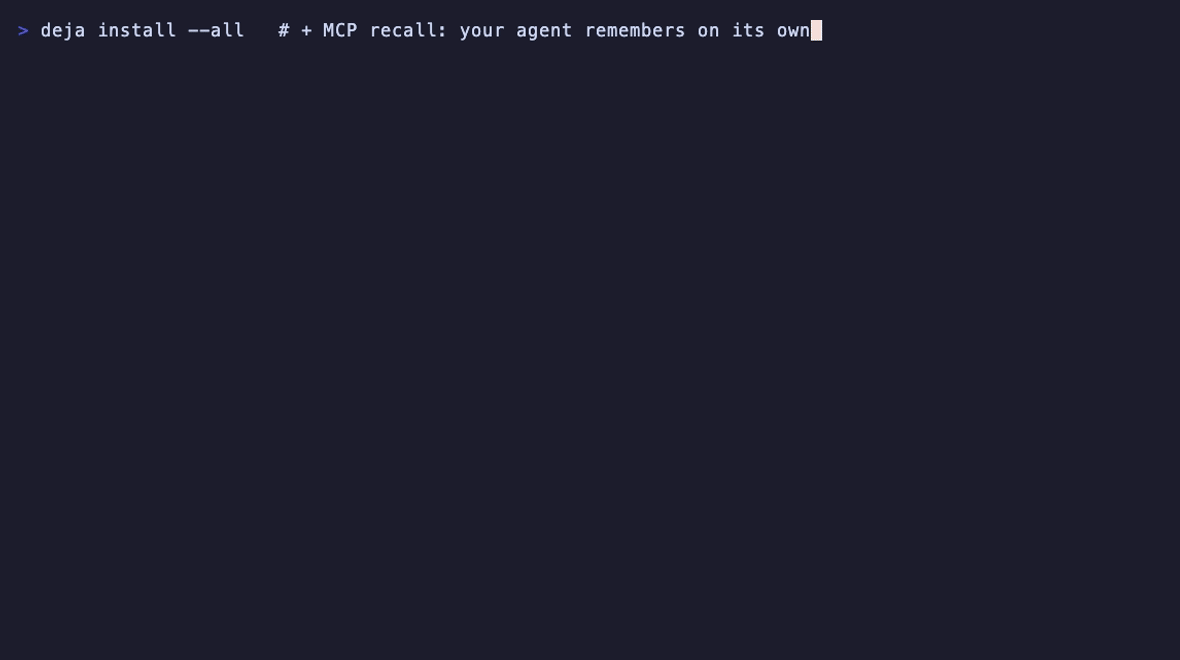
Nobody searched anything — the agent called deja itself. Two real runs against a synthetic corpus: nobody's history is published.
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto
macOS and Linux; ten seconds to install, about ten to index ·
Windows, Homebrew, npm and the rest
I maintain deja-vu, so every driver, the corpus and the scoring rule are in this repository ·
the head-to-head, and how to re-run a row you doubt ·
every run



Docs · Benchmarks · How it compares · Building it into your tool
Found it useful? Star deja-vu on GitHub.
Highlights
- Starts full. Months of history from before you installed it are searchable on day one:
deja "connection pool exhausted" over gigabytes.
- One memory, every agent. A fix found in Codex comes back in Claude Code, Cursor or opencode; all thirty-eight agents read the same index.
- Nobody has to ask. Recall arrives at session start, before a file is edited or a command runs, and after a command fails.
- Survives compaction. Over 43 measured compactions the summary kept 77% of the decisions and 0.2% of the commands; deja hands back the rest (how).
- Indexes the work, not just the talk. The files each turn opened, the commands with their exit status, the exact spans an edit replaced.
- Knows what held.
deja promote <id> --state rejected marks a reverted decision, and every later hit says it was tried and why it was dropped; --state accepted takes the mark back.
- Says when the ground moved. A hit reports 4 files this session touched have changed since, and stays quiet when it cannot tell.
- Local and private. No model, no embeddings, no server. Keys and tokens are stripped as the index is built (privacy).
- Moves with you.
deja sync ssh laptop between machines, no cloud in between; deja handoff --to codex to continue in another agent.
- One Go binary. macOS, Linux and Windows, through Homebrew, Scoop, winget, npm or
go install.
Your own work, wrapped
deja stats --card draws it in the terminal; give it a filename and it writes an
SVG for a profile README. To post it anywhere else, turn it into a
PNG — that page converts it in your own
browser.

The full feature reference lives in the docs.
Install
The two commands at the top are the whole install on macOS and Linux:
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto
Ten seconds to install, about ten to index, and it is useful. The second command wires MCP
recall into every agent it finds, turns on session-start recall where the agent supports
it, and builds the first index so the next session does not pay for it.
Start a new agent session and ask it something you worked on months ago:
have we dealt with jwt refresh rotation before? check your memory
It does not have to be asked, either — with auto-recall the agent already knows what you
solved in that project when the session opens.
Other ways to install, and what to do if you want less than all of it
brew install deja-vu, go install github.com/vshulcz/deja-vu/cmd/deja@latest,
or npx @vshulcz/deja-vu "query" to try it without installing anything. Desktop apps that
take MCP servers as bundles can open the .mcpb from the
latest release; it carries the binary.
Claude Code, Cursor, Qwen and OpenClaw can take the same plugin bundle from
their own marketplaces instead (Codex has a bundle of its own, in the table under
Harnesses with a package of their own).
Copilot CLI installs it too but takes only the skill, so use deja install copilot-auto there:
claude plugin marketplace add vshulcz/deja-vu && claude plugin install deja-vu@deja-vu
On Windows the install script exits with unsupported OS — it is a shell script. Use
Scoop, from the main bucket every Scoop install already has, or winget, which ships with Windows:
scoop install deja-vu
winget install vshulcz.deja-vu
Or take deja-vu_<version>_windows_amd64.zip from the
latest release and put deja.exe on
your PATH, e.g. in %USERPROFILE%\.local\bin.
The binary alone is a complete install for searching: index, search, show, ctx, blame,
--json and redaction need nothing else. deja install is what wires MCP into your agents
and turns on session-start recall — worth having, and optional. On a binary-only setup
deja doctor reports every MCP target as not-wired, which is that setup working as
intended. deja warmup also leaves a skill at ~/.agents/skills/deja-search/SKILL.md
that teaches an agent the CLI contract — deja search --json, ctx, blame, how to read
tier and total — so it knows history is searchable without MCP. The copy in the repo is
skills/deja-search/SKILL.md.
deja install --all is --auto without the session-start recall: agents answer from memory
when they decide to call it, rather than starting each session with it. The
agent setup guide covers what each
harness supports, aider's read-only context file, and the Windows cmd /c deja mcp wrapper.
What gets written into each agent's own guidance file
Install also writes user-level guidance for the harnesses it detects: Claude Code, Codex, opencode, Gemini CLI, Antigravity, Qwen, Kimi Code, pi, Senpi, Copilot, VS Code Copilot Chat, Cursor, Goose, OpenClaw, Hermes, Roo Code, omp, Amp, prime-agent, DeepSeek Harness, Continue, Crush, CodeBuddy Code, WorkBuddy, Zed, TRAE CLI, TRAE IDE and Muse Code each get it in their own guidance file (or under the configured XDG_CONFIG_HOME). Re-run rewrites deja's skill or marked block without changing surrounding user content. Use deja install --all --no-guidance to opt out; Grok Build gets the shared skill in ~/.agents/skills, which is what it reads; the ~/.grok/GROK.md written beside it is for the unrelated community CLI that shares that directory. Cursor has no user-level instructions file, so it gets the shared skill in ~/.agents/skills — one of the four places Cursor reads skills from — read only when something looks relevant rather than every session. Kilo Code, gajae-code, Command Code, Cherry Studio and Reasonix get the skill, and Kiro a steering file, from their own install target.
Privacy
Indexing and search are local. The network is used only by deja update, deja sync ssh,
the version check in deja doctor, and deja embed against an endpoint you configure.
Credentials are stripped as the index is built: cloud and provider keys, tokens and JWTs,
PEM blocks, passwords in URLs or stated in prose. Each becomes [redacted:<kind>] and the
text around it stays searchable. The source transcripts still hold them
(one machine had 84 in 42 sessions):
deja secrets names those sessions without printing a value, and deja secrets --scrub
rewrites the ones it can, keeping the original beside the file.
deja forget drops sessions and keeps them dropped across rebuilds. ~/.config/deja/exclude
skips a project per line, or a whole store with harness:opencode. The
security model has the data flows and what redaction cannot catch.
CLI
$ deja "jwt refresh token"
[claude] api        · Jul 8 · 8f31c0a9 — 2 matches
  login started failing after refresh token rotation; jwt kid mismatch in tests
  fixed by reloading jwks cache after rotateKey and adding a clock-skew test
[codex]  web        · Jul 1 · b77d91e2 — 1 match
  refresh token cookie needed SameSite=Lax in local callback flow
Ask your history
Using what it finds, and moving it between machines
Use what it finds
Move it and check it
Full reference: commands and
JSON output.
The server exposes one tool, deja, with a mode; deja install wires it in. One tool
costs 477 tokens of definitions a turn, against 8,283 for the largest of the seven servers
measured in day zero. The six
older tool names (recall, recall_context, blame, fix, how, remember) still answer.
Arguments and return shapes
q carries whatever the mode asks about. The per-mode names below are still
accepted; they are no longer declared, because the schema is read every turn
whether or not the tool is called.
Supported harnesses
aider · Amp · Antigravity · Claude Code · Cline · Codex CLI · Copilot CLI · VS Code Copilot Chat · Cursor · DeepSeek Harness · Gemini CLI · Goose · Grok Build · Hermes · Kimi Code · omp (Oh My Pi) · OpenClaw · opencode · Continue · Crush · pi · prime-agent (PrimeIntellect) · Qwen Code · Cherry Studio · Senpi · gajae-code · Kimchi Coding · Command Code · ZCode · Kiro · Kilo Code · Roo Code · Zed · CodeWhale · CodeBuddy Code · Reasonix · TRAE CLI · Muse Code.
What each one supports
✅ works · — possible, not built yet · ✕ the harness has no such mechanism · ⚠ waiting on the harness itself · ? not investigated
TRAE IDE is wired, not read: its chats are in an encrypted database. deja install trae-ide
adds the MCP server and the skill, and trae-ide-auto adds hooks, which TRAE IDE runs only
after you turn them on in Settings > Hooks.
Custom store locations go through DEJA_*_ROOT variables, and each agent's own relocation
variable is honored too. The
session format registry documents
the observed paths, record schemas and role mapping per harness, with synthetic fixtures
keeping those descriptions checked against the parsers.
Harnesses with a package of their own
deja install --auto wires every one of these like every other harness, and
that stays the shortest path. They also have a package in their own ecosystem,
for people who install extensions there rather than from a CLI:
Either path works alone, and both together double nothing: each package reads what
deja install already wrote and uses the deja you already have.
The same search is also a skill, for any agent that loads a SKILL.md:
npx skills add https://github.com/vshulcz/deja-vu --skill deja-search   # skills CLI: Claude Code, Cursor, Goose, Copilot…
openclaw skills install @vshulcz/deja-search                            # ClawHub
hermes skills install vshulcz/deja-vu/skills/deja-search                # Hermes
The skill drives the deja binary from the install step above; it does not bundle one.
Semantic recall (optional)
Point deja embed at a local Ollama, LM Studio or OpenAI-compatible endpoint with
DEJA_EMBED_URL and rephrased queries still hit. Without a reachable runtime, lexical
search and MCP recall continue unchanged. OpenAI Platform works with its standard key:
export OPENAI_API_KEY='sk-...'
export DEJA_EMBED_URL='https://api.openai.com/v1/embeddings'
export DEJA_EMBED_MODEL='text-embedding-3-small'
deja embed
Local runtimes, other endpoints, and what vectors cost
With no DEJA_EMBED_URL set, deja probes localhost:11434 and localhost:1234,
so a machine already running Ollama or LM Studio is picked up without being asked.
DEJA_EMBED_OFF=1, or DEJA_EMBED_URL=off, turns that probe off — any other
configured DEJA_EMBED_URL still wins.
For another authenticated OpenAI-compatible endpoint, set DEJA_EMBED_KEY explicitly:
export DEJA_EMBED_URL='https://example.com/v1/embeddings'
export DEJA_EMBED_MODEL='embedding-model'
export DEJA_EMBED_KEY='...'
deja embed
DEJA_EMBED_KEY takes precedence. OPENAI_API_KEY is used automatically only for an
HTTPS api.openai.com URL; it is never implicitly sent to local or third-party endpoints.
The sidecar sits beside the index as .vectors.bin, not inside index.db. Float32 vectors
cost roughly 4 MB per 1k messages for a 1,024 dimension model. A remote endpoint receives
the redacted indexed text, truncated to about 2k characters, but never raw source files.
With Ollama or LM Studio, embedding stays local and needs no key.
Proof
Millisecond lookups, and on LongMemEval-S 88.1% hit@1 (470-question cleaned set) and 87.4% hit@1 on all 500 questions;
on LoCoMo retrieval, 70.5% hit@1. On a task this machine had already solved, 58% fewer
tokens: eleven runs an arm, 53,558 against 126,222 with nothing wired, and 52,815 against
103,443 on a later build with the arms alternated. Both retrieval harnesses ship in this repo
and run on the public datasets in minutes: benchmarks ·
what one task costs.
The rest is measured by deja bench:
deja bench recall     # ranking floor: 100 queries, half Russian, CI fails if recall drops
deja bench context    # 30 seeded task chains plus five negative controls
deja bench block      # does the answer survive into what deja hands over
deja bench prompt     # what the per-prompt hook fires on, and what it fires on wrongly
deja bench ingest     # what an update costs: unchanged, a turn, a new transcript, a rename, a rewrite
deja bench read       # what it costs to read a database-backed store, and what one long value does to it
What the in-repo benches measure, and lookup cost on a real store
bench block asks the question the others cannot: with the right session in
hand, does the block carry what that session settled. Eight sessions discuss each
subject and one of them settles it, in the middle of its own transcript rather
than at the end — so the baseline arm, the newest turns of the top hit, scores
zero and an arm above zero had to choose.
The context experiment compares deja-recall against full-history, naive grep and cold
context. With the default seed:
Same fact coverage as grepping the raw logs for about 250x fewer tokens, and about 70x
fewer than replaying the matched sessions in full, while injecting nothing on the chains
where no prior fact is relevant. The corpus generator and the relevance labels are
ordinary reviewed Go. Audit what "relevant" means before trusting any figure, ours
included.
Measured on a real store of 2,419 sessions and 179k messages, 1.9 GB of
transcripts:
The same store has since grown to 2,754 sessions, 358k messages and 5.7 GB.
A cold full build over it takes 71 s and writes a 232 MB index — 4% of the
corpus, because the share falls as transcripts repeat themselves — and the
end-to-end median is unchanged at 0.25 s.
The index is incremental. When a session file grows, only that file is re-read.
How it works
Local inverted index in ~/.cache/deja: parse the JSONL and SQLite stores, redact
credentials, write records.bin plus token buckets, and track per-file state in
manifest.gob so repeat runs only ingest what changed. The MCP server, stats, share and
sync all read that one index. Details in docs/ARCHITECTURE.md.
FAQ
Does anything leave my machine?
No, unless you ask it to. See the
data flows.
What about secrets already in my logs?
They stay in the original harness files, which
are your agent's data; deja secrets names the sessions that carry them so you can rotate
and delete, and --scrub rewrites the transcripts it can reach. Known shapes — AWS keys, api_key=/token= assignments, bearer
tokens and bare JWTs, PEM blocks, provider tokens, high-entropy values — are stripped as
the index is built, so they do not reach digests, shares or sync exports. Pattern matching
is not secret detection: a shape it does not know can pass through. See the
security model.
Will it slow my agent down?
A recall is a lexical lookup against a local index:
0.7–0.8 ms median, and nothing waits on a model. A hook adds the process start and a
freshness check over your stores on top of that — tens of milliseconds on a store of
a few gigabytes.
Do I have to change how I work?
No. The agent calls recall itself, and with
auto-recall it already knows the project's prior decisions when the session opens.
How is this different from the other memory tools?
engram is the strongest of the
record-forward tools and worth your time if that model fits you; it still starts empty and
knows only what an agent chose to save. The
full comparison covers 15 of them.
Where is Claude Code session history stored, and can I search it?
Under
~/.claude/projects, one JSONL file per session; Codex keeps ~/.codex/sessions, Cursor a
SQLite state.vscdb. deja search reads them all in place, deja last lists the recent
sessions of every agent, and deja view opens the whole history as one local page. Paths
for each agent: where sessions are stored.
My Claude Code session history disappeared. Is it gone?
Claude Code deletes transcripts
older than 30 days (cleanupPeriodDays in ~/.claude/settings.json), and claude --resume lists
only what is left. A session deja indexed before the cleanup stays searchable after the
file is gone. Details: session files on disk.
What about Windows?
Builds exist and CI runs the suite there. macOS and Linux are the
battle-tested paths. Field reports welcome in #9.
How do I wipe everything?
deja uninstall --all
rm -rf ~/.cache/deja
Guides
Written for the situation rather than the feature:
Per harness: opencode · DeepSeek Harness · Kimi Code · Zed · Grok Build · Gemini CLI · Qwen Code · OpenClaw · Goose · Cline · pi and omp · Hermes
Try it on your own history
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto
Ten seconds to install, about ten to index. The next session your agent opens, it
already knows what you solved in that project — including everything from before
you installed this.
Contributing
make build test lint, then CONTRIBUTING.md. Adding a harness starts in
the parser registry. Priorities and non-goals are in
ROADMAP.md. Good first issues are labeled.
Support
Bugs and questions go to issues.
Anything you think is exploitable goes through the private advisory link in
SECURITY.md instead. What deja reads, what it never sends
anywhere, and how to exclude a project or forget a session is under
Privacy.
License
MIT © Vladislav Shulcz




